About
I am a second-year PhD student in the Caltech Rigorous Systems Research Group, advised by Prof. Adam Wierman and Prof. Eric Mazumdar at the Computing + Mathematical Sciences (CMS) Department, California Institute of Technology. Most people call me Ray. Before joining Caltech, I obtained my B.Sc. degree at Peking University.
Research
My research develops theoretical and algorithmic foundations for multi-agent alignment, ensuring AI agents, including LLMs, can reliably cooperate with each other and with people. I approach this along three directions: (1) grounding agents in behavioral game theory so they can coordinate with novel partners; (2) designing cooperative multi-agent systems that generalize to new environments and scale to more agents; and (3) building robust learning and optimization methods that transfer across distribution shifts. I’m always happy to connect; feel free to reach out if you’d like to discuss research, collaborations, or entrepreneurial opportunities.
News
Latest Posts
Selected Publications
Behaviorally-Grounded AI Agents
Incorporating insights from behavioral economics and game theory into agent training in a principled way, enabling AI agents (including LLMs) to robustly cooperate with novel partners.
-
 Training Generalizable Collaborative Agents via Strategic Risk AversionNeurIPS (oral, top 0.3%), 2026
-
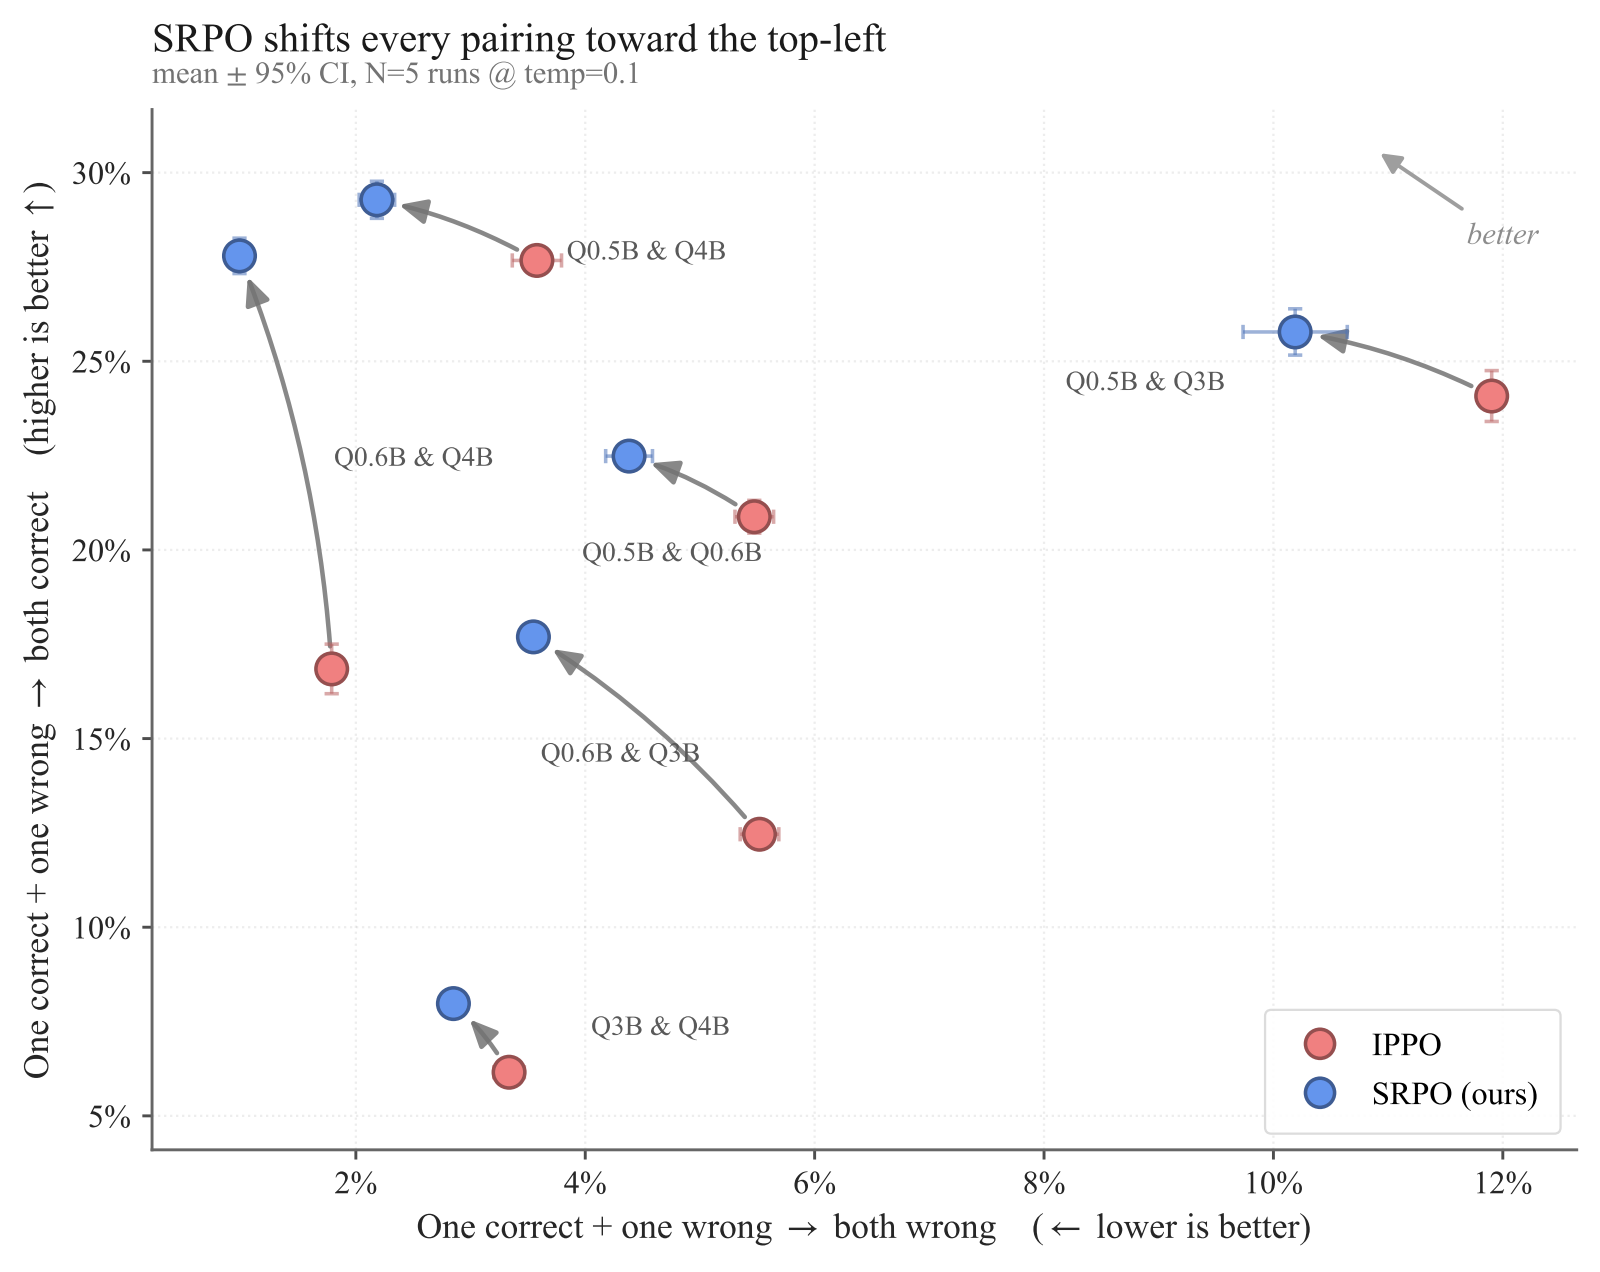 Behavioral Game Theory for Collaborative LLM AgentsCOLM Workshop on Agent Behavior (spotlight oral), 2026
Generalizable Multi-Agent Cooperation
Building cooperative multi-agent systems that generalize to novel environments and scale gracefully through robust value factorization, diversity-driven scaling, and knowledge-centric self-improvement.
-
 Distributionally Robust Cooperative Multi-Agent Reinforcement Learning via Robust Value FactorizationICLR, 2026
-
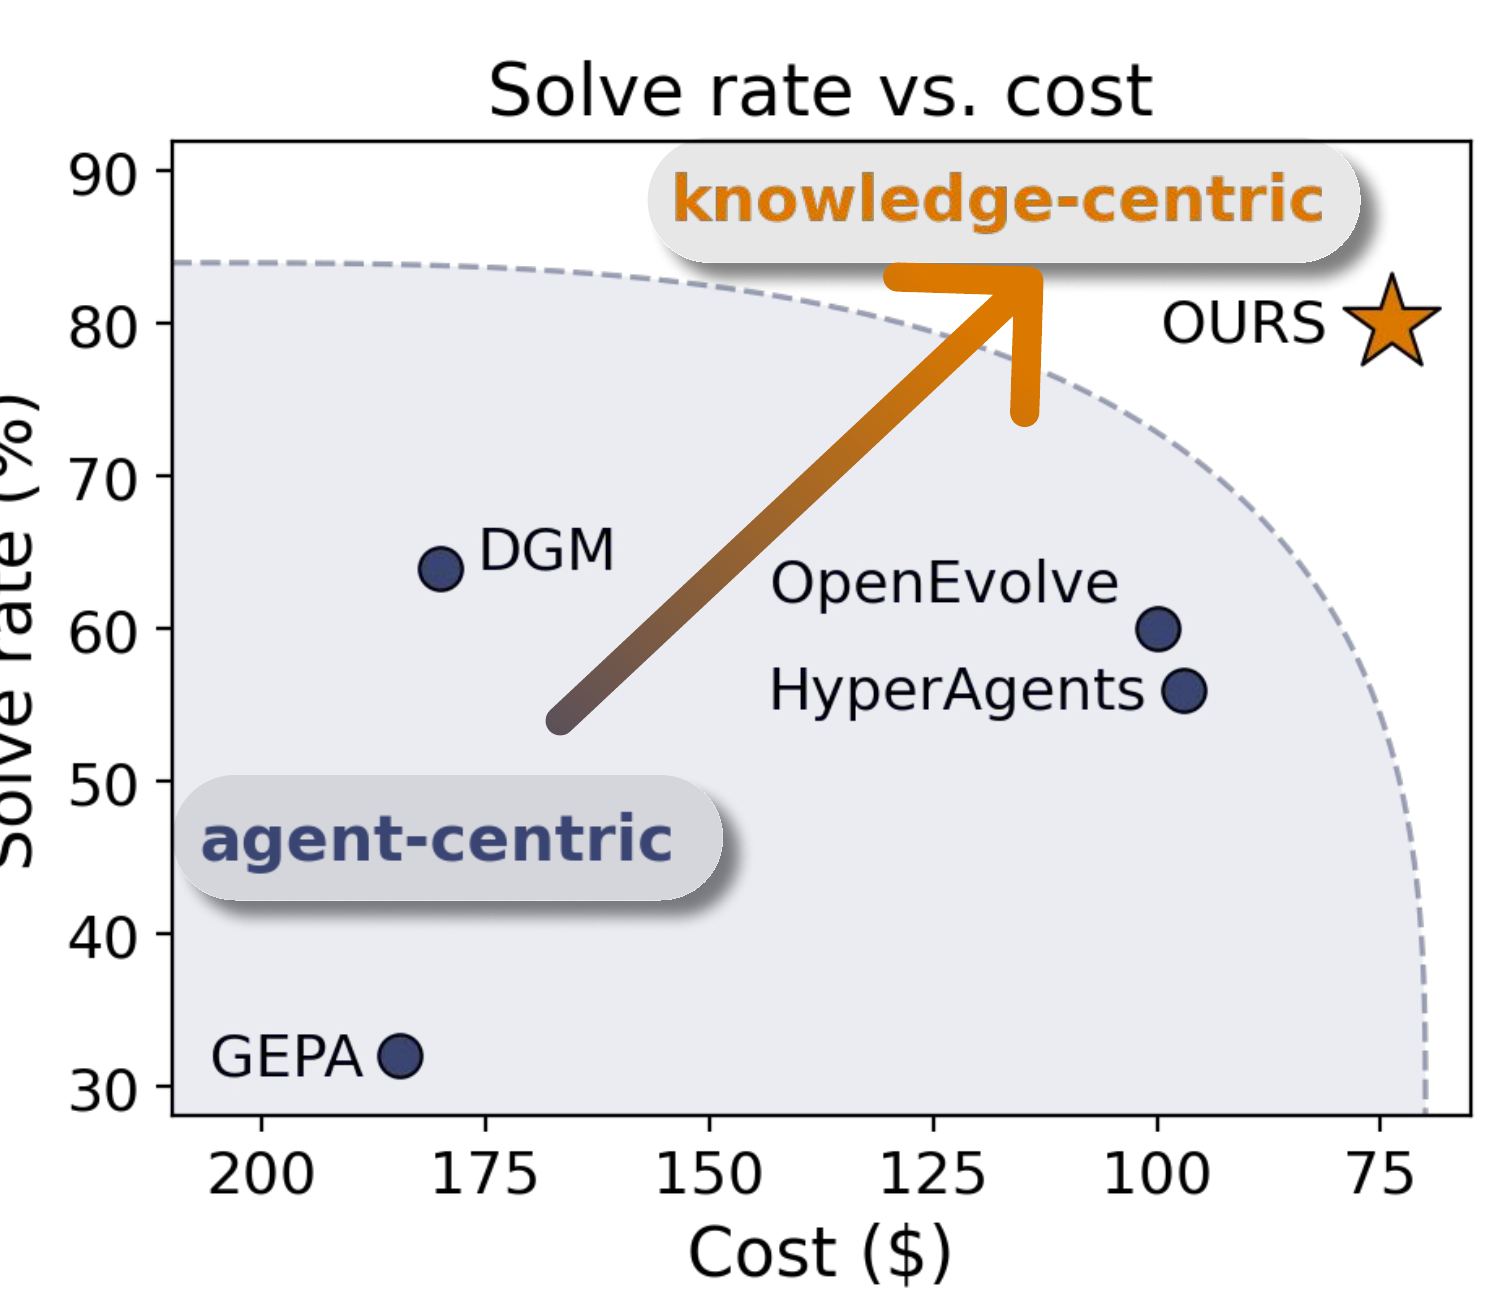 Knowledge-Centric Self-ImprovementCOLM Workshop on Context Beyond the Window: Persistent Knowledge in Language Models, 2026
-
 Understanding Agent Scaling in LLM-Based Multi-Agent Systems via DiversityarXiv preprint, 2026
Learning & Optimization under Distribution Shift
Making reinforcement learning and optimization provably robust when training and deployment conditions diverge, whether through dynamics mismatch, sim-to-real gaps, or distributional uncertainty.
-

-
 Hybrid Transfer Reinforcement Learning: Provable Sample Efficiency From Shifted-dynamics DataAISTATS (oral, top 2%), 2025
-
 Decision-Dependent Distributionally Robust Optimization with Application to Dynamic PricingIEEE CDC, 2025
-
